
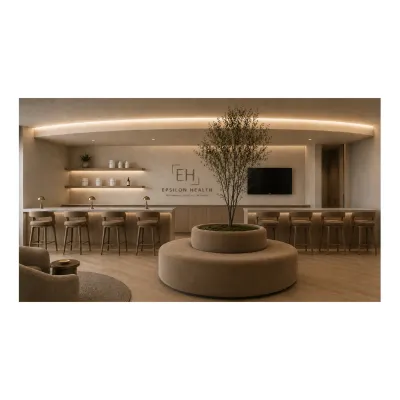
Why this role stands out
This role offers a unique opportunity to build foundational ML infrastructure for a company making a significant impact on healthcare diagnostics, fostering immense learning and career growth. You'll thrive here if you're a skilled engineer eager to collaborate with researchers and develop cutting-edge systems that accelerate AI innovation. Apply now to join a mission-driven team and shape the future of medical imaging.
Quick overview
Job description
About Us
Epsilon Health is transforming medical imaging and diagnostics by bringing frontier AI into clinical practice. We're tackling some of healthcare's most critical challenges, building technology that directly improves patient outcomes.
This year, we've served over 300,000 patients and now serve 3,000+ daily, working with some of the largest medical institutions in the U.S. By year-end, we're on track to interpret 1% of all daily U.S. X-rays.
Our research team brings experience from DeepMind and Meta, powered by one of the industry's most comprehensive proprietary medical imaging datasets, continuously enriched by real-world clinical data. Together, we're building a future where frontier AI helps save millions of lives today, not tomorrow.
Recently out of stealth, we're proudly backed by Jack Altman, Uncork Capital, Renegade Partners, and AlleyCorp, one of NYC's most active healthcare venture firms.
Role Overview
We’re looking for an ML infrastructure engineer to design and build the core systems that enable scalable, efficient training of large models for deployment and research. Your goal is to make experimentation and training at Epsilon Health fast and reliable to ensure our research teams can focus on science rather than system bottlenecks.
Sitting in the Engineering team and working closely with research, you'll own the distributed training and reinforcement learning infrastructure our foundation-model and post-training work runs on, and the inference and evaluation systems that carry models from experimentation into production.
Key Responsibilities
Partner directly with researchers to deeply understand their workflows, then anticipate and design for how those needs will change
Build a distributed training infrastructure for foundation models on large-scale medical imaging, including the long-context parallelism and checkpointing that volumetric CT/MR training demands.
Build high-throughput data loading and preprocessing that keeps GPUs saturated on large volumetric and multimodal datasets.
Partner with researchers to prototype new ideas and translate them into production-ready code, owning end-to-end delivery from experimentation through deployment and monitoring.
Contribute to production serving and deployment pipelines (model rollout, canary deployments, and monitoring) alongside the backend team.
Build the reinforcement learning training stack (high-throughput rollout generation, reward-model serving, and experience collection), enabling the research team to run online, multi-reward RL at scale.
Qualifications
6+ years of experience designing, building, and operating large-scale distributed systems or infrastructure in production
Have 2+ years of experience building ML infrastructure or systems in production
Strong Python skills and expertise in PyTorch or JAX
Experience and familiarity with the compute, tooling, and workflow needs of large-scale machine learning research
Experience building infrastructure or platforms specifically for research or machine learning workflows
Deep experience building and operating Kubernetes and cloud infrastructure at scale
Experience with distributed training at scale (FSDP, DeepSpeed, or Megatron-style parallelism) and the systems concerns of keeping large GPU jobs efficient
Prior experience as a technical lead or mentor for other engineers
Preferred Qualifications
Experience operating in a startup or startup-like environment, i.e. a small, fast-moving team with high autonomy
Experience building reinforcement learning training infrastructure: rollout generation, reward-model serving, or online/off-policy learning systems
Experience with high-performance inference and serving (vLLM, SGLang, TensorRT, or Triton) for both training-time rollouts and production
Experience optimizing inference and serving for large models: batching, KV/prompt caching, quantization, and low-latency, high-throughput sampling.
Experience optimizing training performance: parallelism, distributed communication, mixed/low precision, and utilization.
Experience building internal training or experimentation platforms used by research teams, supporting A/B testing and experimentation workflows
Familiarity with vision-language models (VLMs) or multimodal architectures
Haystack's AI agent can fill in and submit this application for you. How AI auto apply works
Will your resume get past this employer's screening? Check your resume against this job, free
Similar jobs
- AI

Senior Software Engineer, Distributed SimulationRecently posted Auto Apply
Anduril Industries · Seattle · Hybrid · Posted 20 Nov 2026 🇺🇸
RoboticsComputer VisionC+++4Technology$191k - $253k/yr - AT
Senior HIL Validation & Integration Engineer - AutomotiveRecently posted Auto Apply
ALTEN Technology USA · Auburn Hills · Hybrid · Posted 20 Nov 2026 🇺🇸
ADASSimulinkVehicle DynamicsAutomotiveSalary not listed - FO
Senior Test Software EngineerRecently posted Auto Apply
Focus · United States · Remote · Posted 20 Nov 2026 🇺🇸
MicroservicesPlaywrightTypeScript+2Technology$135k - $170k/yr - WA
Senior Software Engineer - Sensor Systems, Robot SoftwareRecently posted Auto Apply
Wayve · Sunnyvale · Hybrid · Posted 19 Nov 2026 🇺🇸
RoboticsC++ROS+2Technology$200k - $250k/yr - UI

Senior Software Engineer -AIRecently posted Auto Apply
Uipath · Bellevue · On-site · Posted 20 Nov 2026 🇺🇸
MicroservicesC#Java+5Technology$180k - $230k/yr - UF
Application Lead Auto Apply
Uft · Irving · On-site 🇺🇸
SQLETLERP+10Salary not listed - PA

Member of Technical Staff, Core InfrastructureRecently posted Auto Apply
Parallel · San Francisco · On-site · Posted 20 Nov 2026 🇺🇸
GCPRustEnvoy+13$150k - $300k/yr - EX
Senior Infrastructure Software Engineer (Austin, TX)Recently posted Auto Apply
Exowatt · Austin · On-site · Posted 20 Nov 2026 🇺🇸
OnboardingSOC 2Compliance+6TechnologySalary not listed - RA
Sr. Deployment EngineerRecently posted Auto Apply
Robust Ai · San Carlos · Remote · Posted 20 Nov 2026 🇺🇸
SQLGitRobotics+9TechnologySalary not listed - QU
Software Engineer Auto Apply
Questanalytics · United States · Remote · Posted 9 Nov 2026 🇺🇸
SQLGitAWS+10TechnologySalary not listed - EA

Software Engineer, Cybersecurity Benchmarks Auto Apply
Epoch Ai · United States · Remote · Posted 10 Nov 2026 🇺🇸
Machine LearningTechnology$150k - $350k/yr - SA
Staff Software EngineerRecently posted Auto Apply
Samsara · United States · Remote · Posted 19 Nov 2026 🇺🇸
GraphQLIoTLLM+2Technology$154.7k/yr