Quick Overview
Job Description
About Bureau
Bureau is a unified risk decisioning platform for Compliance, Fraud, and Transaction risks. Our platform is a single decision-making engine, powered by a 1 billion+ identity knowledge graph. Over 150 Banks, fintechs, retailers, and digital platforms use Bureau to verify identities faster and stop fraud earlier globally.
Bureau has raised $50M+ from renowned Silicon Valley and global investors including Sorenson Capital and PayPal Ventures and is expanding rapidly from APAC to Americas, Europe, and beyond.
Why Bureau?
Bureau is building the infrastructure that makes digital identities and transactions safe and trustworthy for billions of people. The mission is big, the problems are complex, and the impact is real.
We hire people who want that level of responsibility. People who move fast, build systems from scratch, and care deeply about turning strategy into execution. If you want predictability or narrow scope, this won't be your place. If you want to shape how a scaling global company operates—keep reading.
What You'll Do
Build and maintain batch and streaming pipelines that ingest, clean, and transform data from device SDKs, internal services, partner APIs, and third-party data providers
Write and own backend services and RESTful APIs that serve data to internal teams and to real-time decisioning paths
Develop Airflow DAGs powering reporting, compliance analytics, model training, and feature pipelines, and keep them healthy day to day
Write Spark jobs and SQL transformations against our data lake, and tune them when they get slow or expensive
Add monitoring, alerting, and data quality checks to the pipelines you own so problems surface before a stakeholder notices
Debug production issues across the stack: a Kafka consumer lagging, a schema change breaking downstream, a query that got 10x slower after a data volume jump
Work with the infrastructure your pipelines and services run on — containers, deployments, cluster configs — and help keep it stable and cost-sane
Contribute to our identity graph work, helping model relationships between entities to surface fraud rings and hidden linkages
Write documentation and tests, participate in design reviews, and help keep our schemas and contracts sane as the system grows
What You'll Bring
Must have
1–3 years of professional software engineering experience, with meaningful exposure to data-intensive systems
Strong programming skills in Python, Java, or Scala, and the ability to write production-quality, tested code
Strong SQL: joins, window functions, aggregations, and enough of a mental model of query execution to know why something is slow
Working understanding of databases, including the difference between OLTP and OLAP systems and when each is appropriate
Hands-on experience with at least one distributed data processing framework (Spark preferred) or a genuine willingness to ramp up quickly
Experience building or maintaining backend services and REST APIs
Familiarity with a major cloud platform (AWS preferred) and core services like S3, EC2, and managed databases
Solid computer science fundamentals: data structures, concurrency, and the basics of distributed systems
Comfort with Git, code review, and CI/CD
Nice to have
Infrastructure and systems knowledge — Docker, Kubernetes, Terraform or similar IaC, and a working sense of how services get deployed, scaled, and monitored in production
Experience running or tuning distributed workloads: cluster sizing, resource tuning, or tracking down a bottleneck between compute and storage
Exposure to Kafka or MSK, or any streaming/event-driven system
Experience with Airflow or a similar orchestration tool
Exposure to EMR, Athena, ClickHouse, Databricks, or Snowflake
Awareness of lakehouse table formats such as Iceberg, Delta Lake, or Hudi
Familiarity with observability tooling — Prometheus, Grafana, Datadog, or equivalent
Any experience with graph databases (Neo4j, TigerGraph, Amazon Neptune)
Interest in or exposure to fraud, risk, identity, fintech, or other high-stakes real-time domains
Exposure to ML workflows: feature pipelines, training data preparation, or model serving
What We Look For
You debug rather than guess, and you can explain what actually went wrong
You ask what the data is for before deciding how to model it
You're curious about the layer below the one you work in — how your code actually runs, where it fails, what it costs
You're comfortable being new to a tool and getting productive in it quickly
You care that numbers are right, because at Bureau a wrong number is a wrong risk decision
Our Culture
We hire self-motivated people and get out of their way
We value performance, not hours worked
Speed, ownership, and impact matter most
Compensation
Competitive salary + potential equity
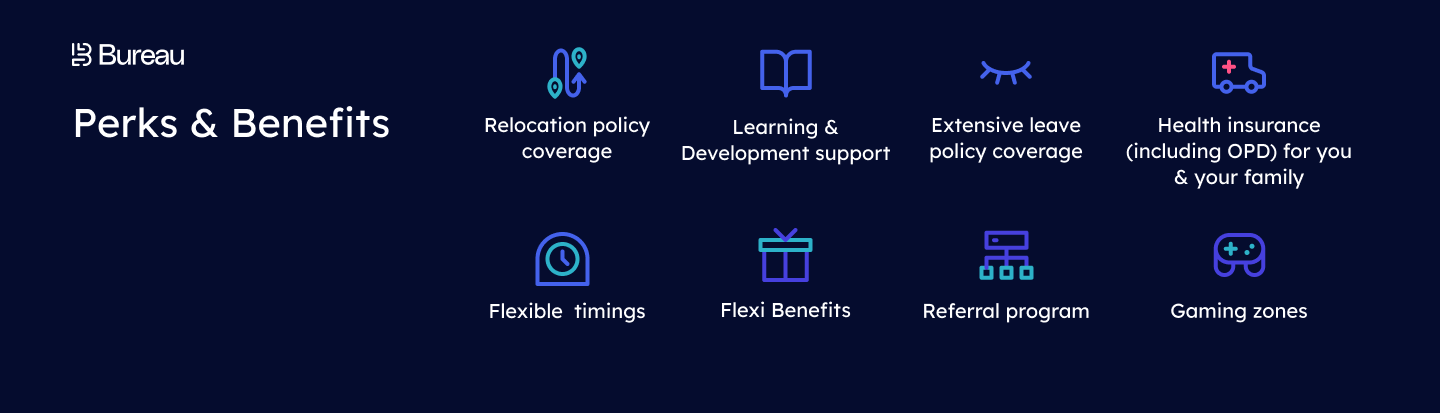
Health benefits, flexible PTO, learning budget
Similar jobs
- EU
Data Management Specialist
NewEurofins
Bengaluru, KA🇮🇳Hybrid9 hours agoSQLTechnology - WA
Data Platform Engineering
NewWeekday AI
Hyderabad, Telangana🇮🇳On-siteYesterdaySQLETLScrum+2 - VE
MySQL Database Engineer
NewVerifone
Bengaluru🇮🇳13 hours agoMySQLOracleRust+24Technology - RO
Lead Data Engineer
NewReferrals Only
Bengaluru🇮🇳YesterdayGCPSQLTDD+1Technology - RO
Senior Data Engineer
NewReferrals Only
Bengaluru🇮🇳YesterdayGCPSQLAWS+3Technology - VA
Senior Data Engineer
NewValtech
Bengaluru🇮🇳YesterdayDockerGCPMicroservices+29Technology